
DimensionLab
Case studies
Measured results from physics models trained, evaluated and deployed with Frontier: the data, the method and the numbers, including where the models fall short.
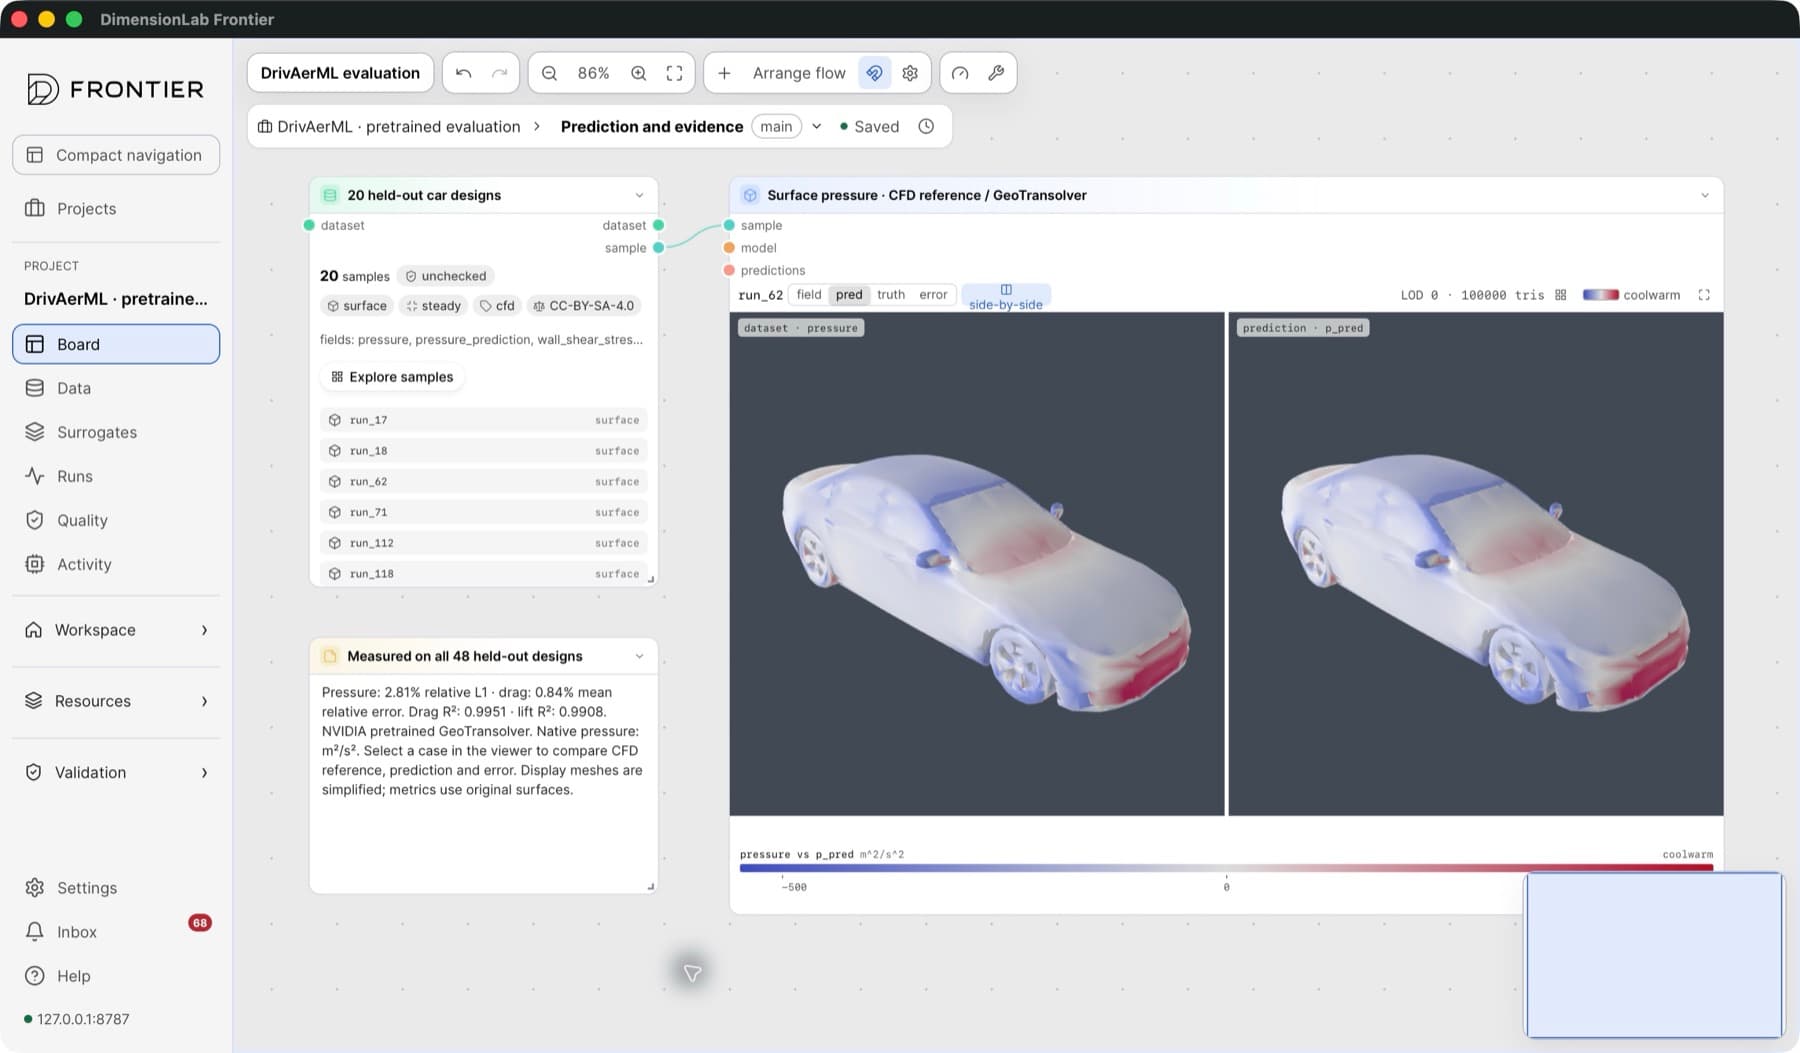
Evaluating NVIDIA's pretrained GeoTransolver on all 48 held-out DrivAerML cars
A Frontier study that ran NVIDIA's published GeoTransolver checkpoint against every held-out DrivAerML design, with hashes for the model, data and split, for about $13 of cloud GPU time. Drag R² 0.995, mean drag error 0.84%.
- held-out car designs evaluated
- 48 / 48
- drag force R²
- 0.995
- mean relative drag error
- 0.84%
- single H100 pod, end to end
- 3.3 h
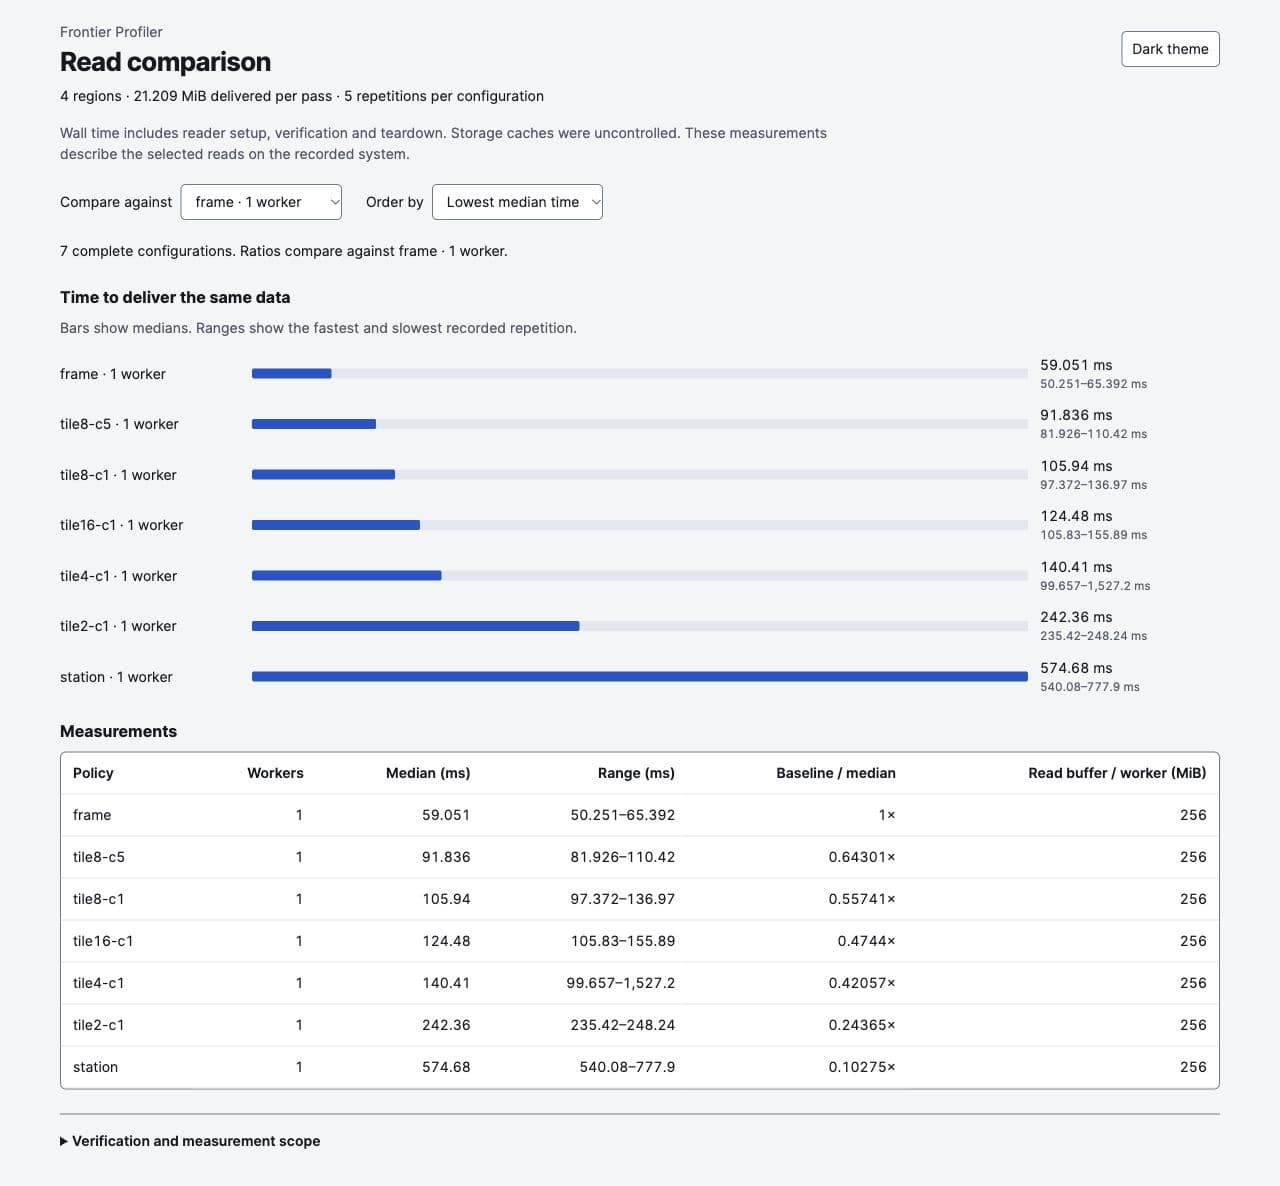
Reading only what you need: bounded scientific data reads and 134-million-voxel volumes on an 8 GB GPU
Frontier studies of its data layer: ArrayRoute's bounded reads on real ERA5 data, million-sample dataset previews in milliseconds, 75% fewer bytes for overlapping readers, and NanoVDB volumes at 10⁸ nodes in NVIDIA Omniverse.
- faster station read on real ERA5 (124.8 → 1.47 ms)
- 85×
- preview of a 1,000,000-sample dataset
- 3.7 ms
- fewer bytes for four overlapping readers
- 75%
- to open a 512³ (134 M-node) volume
- 1.1 s
From 21% to 4.9% surface-pressure error on AhmedML, for $15.54 of cloud GPU
A Frontier study that ingested all 500 AhmedML simulations, trained reference surrogates on rented GPUs, and certified them against a benchmark with calibrated drag intervals. Test pressure error fell from 0.213 to 0.049 relative L2.
- test surface-pressure rel-L2 (was 0.213)
- 0.049
- surface-pressure R² on 50 test designs
- 0.996
- conformal Cd interval coverage (45/50)
- 90%
- total RunPod spend
- $15.54
One verified package, every target: TensorRT at 1.8× PyTorch speed, a 1.7 MB edge model, and an FMI co-simulation unit
A Frontier study that took trained CFD surrogates from checkpoint to TensorRT, ONNX, edge CPU, an HTTP service and an FMI 2.0 FMU, with each export's parity and accuracy measured before it was stored. Total cloud cost: $0.44.
- TensorRT FP32 vs PyTorch at 131k points
- 1.8×
- TensorRT FP32 parity (relative L2)
- 3e-7
- faster on one ARM core with dynamic INT8
- 4.3×
- total RunPod spend
- $0.44
Earlier work
These projects predate Frontier. They are kept for reference and are not related to any product or service we currently offer.
External Aerodynamics with Physics-Informed Neural Networks
Siml.ai is well-positioned for building AI models for aerodynamics that are 100-1000x faster than traditional CFD methods
Boosting The Development of Bone Fixator Prototype
Biomedical Engineering Company Developing New Medical Tools
Ensuring There's Right Temperature in a Tiny Off-Grid House
Company that designs and builds small capsule off-grid houses was looking to find the best insulation material
Analyzing The River Flows into Hydropower Plant
A hydropower plant design company used Siml.ai to analyze the design of the intake structure